Ecode Dash Blog
Data Engineer vs Data Scientist: Which Role Should You Hire First?
A practical guide for CTOs and engineering leaders on the data engineer vs data scientist hiring decision. It covers pipeline readiness, data quality, what each role should deliver in the first 90 days, the signs that you hired in the wrong order, and how staff augmentation lets you add the second role when your data foundation is ready.
Many companies that struggle with analytics did not hire the wrong people. They hired the right people in the wrong order. The data engineer vs data scientist decision is a sequencing problem: a data scientist's models are only as reliable as the pipelines feeding them, and a data engineer's pipelines create value only when someone turns clean data into decisions.
Key takeaways
-
Hire a data engineer first if your data is scattered, refreshed by hand or disputed between teams.
-
Hire a data scientist first only when a trusted, central data store already exists and you have a specific business question to answer.
-
Data quality decides how much of a data scientist's time goes into modeling instead of cleanup.
-
Each role should show measurable output within 90 days. If that output is missing, check the order you hired in before you blame the person.
-
Staff augmentation lets you add the second role for a defined window instead of committing to a long recruiting cycle too early.
-
Data engineer core job: Builds and maintains the pipelines, warehouses and data models that move and store data reliably.
-
Data scientist core job: Analyzes data, builds statistical and machine learning models, and turns findings into predictions and recommendations.
-
Hire the engineer first when: Data lives in many tools, refreshes manually or produces conflicting numbers.
-
Hire the scientist first when: A clean warehouse exists and a high-value question is waiting for an answer.
-
First 90 days, engineer: Automated ingestion, tested data models, monitoring and documented metrics.
-
First 90 days, scientist: Baseline analysis, a first working model or forecast, and one measured experiment.
-
2026 demand signal: Data engineers rated 78% and AI/ML engineers 94% on EcodeDash's 2026 demand index (EcodeDash, citing Grand View Research, Gartner and Qubit Labs 2025 to 2026 reports).
Data engineer vs data scientist: what is the actual difference?
A data engineer builds the infrastructure that collects, moves, cleans and stores data so the business can trust it. A data scientist uses that data to answer questions, build predictive models and test hypotheses. The data engineer owns the reliability of the data, and the data scientist owns the insight drawn from it. One role produces the raw material the other depends on.
In practice, a data engineer works on data pipelines (automated processes that move data from source systems such as your product database, billing platform and CRM into a central store). Data engineers design ETL or ELT jobs (extract, transform, load, or load first and transform inside the warehouse), manage a data warehouse such as Snowflake, BigQuery or Redshift, and handle orchestration, which means scheduling and monitoring those jobs with tools like Airflow or Dagster.
A data scientist works further downstream. Typical output includes churn prediction, demand forecasting, pricing analysis, recommendation logic and the statistical design of A/B tests. Two neighboring roles often come up in the same conversation. A data analyst reports on what already happened using SQL and BI dashboards. An ML engineer takes a data scientist's model and runs it reliably in production, a discipline often called MLOps.
Is your data pipeline ready for a data scientist?
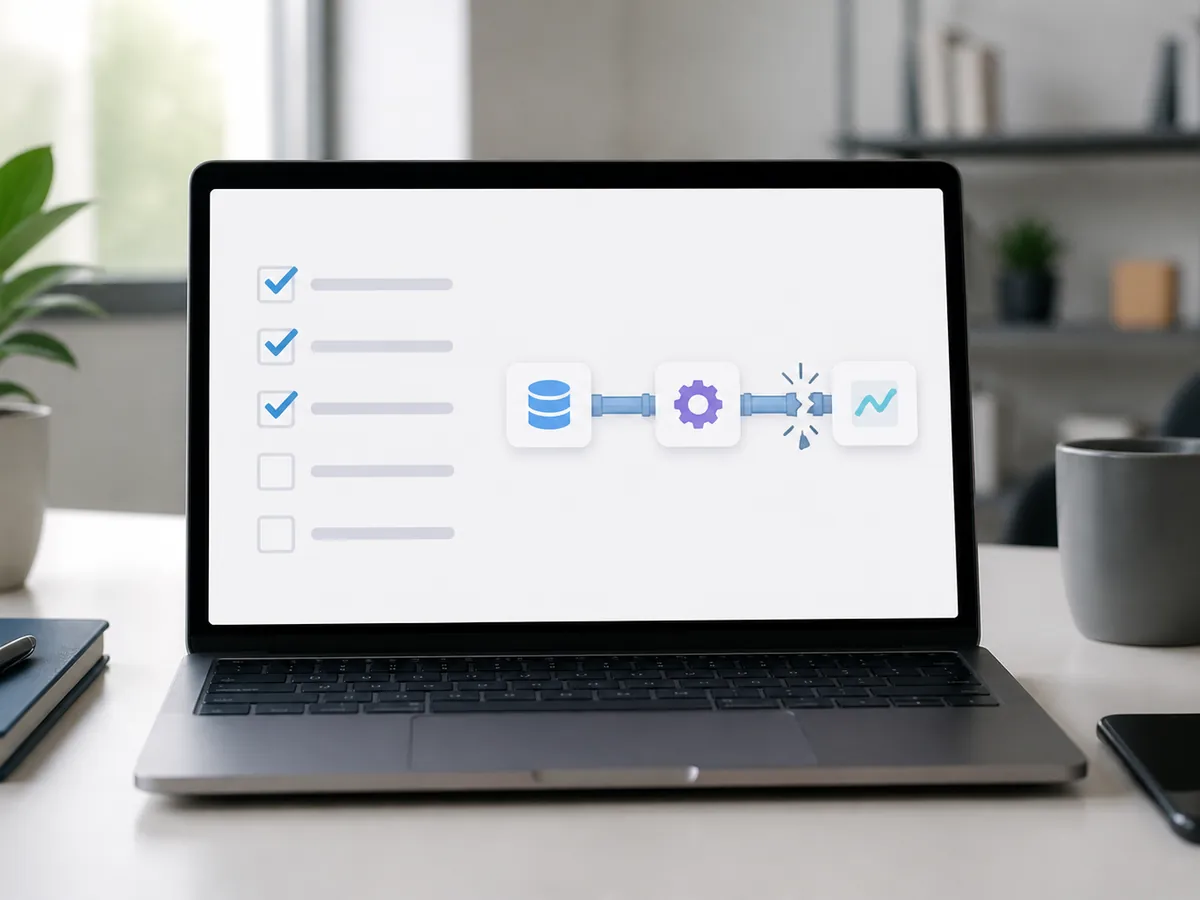
A data pipeline is ready for a data scientist when core business data lands automatically in one central store, refreshes on a predictable schedule and matches the numbers finance and product already trust. If analysts still export CSV files, reconcile spreadsheets by hand or argue about which revenue figure is correct, the pipeline is not ready.
Run this five-point readiness check before you open a data science requisition:
- Centralized storage: Product events, billing, CRM and support data sit in one warehouse or lakehouse rather than in separate tools.
- Automated ingestion: No critical dataset depends on someone running a manual export every Monday.
- Agreed definitions: Terms such as active user, churned account and net revenue have one documented definition.
- Historical depth: You have enough consistent history to train on. For churn or forecasting work, a year or more of stable data is a sensible practical minimum.
- Ownership and monitoring: Someone gets alerted when a pipeline fails or a table stops updating.
If you answer no to two or more of these, the data engineer should come first. A data scientist hired into that environment will spend the early months doing data engineering work, usually with fewer tools and less rigor than a specialist would bring.
How does data quality change the hiring order?
Data quality decides how much of a data scientist's time goes into science rather than cleanup. When duplicate records, missing values, broken event tracking and schema drift are common, a data scientist repairs inputs week after week instead of modeling. A data engineer fixes those problems at the source, so every downstream user benefits once.
Schema drift is what happens when a source system changes its structure without warning, for example when a product team renames an event or a billing field changes type. Without automated tests and data contracts (agreed rules about what a dataset must contain), those changes silently break dashboards and models.
Consider an illustrative scenario. A Series B SaaS company wants a churn model, so it hires a senior data scientist. Product events sit in PostgreSQL, subscriptions in Stripe and account health in HubSpot, with no shared customer ID across the three. The data scientist spends ten weeks writing one-off joins in notebooks, the model ships late, and nobody can rerun it after the next schema change. The same company, with a data engineer hired six weeks earlier, would have had a unified customer table and a scheduled pipeline before modeling began.
When should you hire a data engineer first?
You should hire a data engineer first when your bottleneck is access to reliable data rather than analysis of it. That covers most early-stage and scaling companies whose data sits across SaaS tools, whose reporting is assembled by hand, or who plan AI features that need governed, production-grade data.
Common triggers include:
- Leadership dashboards that disagree with finance reports.
- An AI or machine learning roadmap with no feature store, the shared repository of model-ready variables that data scientists draw from.
- A planned warehouse migration, customer data platform (CDP) rollout or compliance requirement around data lineage, which is the record of where each data point came from and how it changed.
- Engineers on the product team pulled away from roadmap work to fix reporting queries.
When should you hire a data scientist first?
You should hire a data scientist first when a trusted data foundation already exists and a specific, high-value question is waiting for an answer. Companies with managed ingestion tools, a maintained warehouse and an analytics engineer often have enough infrastructure for a data scientist to produce results quickly.
Good signs include a clear question with a revenue link (which accounts will churn next quarter, what price point maximizes expansion), stable historical data, and a team ready to act on the findings. Without a decision owner, even a strong model ends up as a slide deck.
What does each role deliver in the first 90 days?
In the first 90 days, a data engineer should deliver automated, tested pipelines and a set of trusted core tables. A data scientist should deliver a baseline analysis, a first working model or forecast, and one measured experiment. If either role cannot point to these outputs, the issue is often sequencing rather than skill.
Data engineer: first 90 days
- Days 1 to 30: Audit sources, map data flows, and stabilize the most broken or most important pipeline.
- Days 31 to 60: Automate ingestion for core systems, build tested data models (often in dbt, a SQL-based transformation framework), and document metric definitions.
- Days 61 to 90: Add monitoring and alerting, set access controls, and deliver a single source of truth for revenue, users and retention.
Data scientist: first 90 days
- Days 1 to 30: Learn the business model, profile available data and agree on one priority question with a decision owner.
- Days 31 to 60: Produce a baseline analysis and a first model, such as a churn score or demand forecast, with its limits clearly stated.
- Days 61 to 90: Run one controlled experiment or pilot, measure impact against the baseline, and define what production deployment would require.
What are the signs you hired in the wrong order?
The clearest sign of hiring in the wrong order is a mismatch between the work a person was hired to do and the work they actually do each week. A data scientist who mostly cleans data, or a data engineer whose polished pipelines nobody queries, is a sequencing problem rather than a performance problem.
You probably hired the data scientist too early if:
- Most of their time goes into data cleaning and one-off extracts.
- Models work in notebooks but cannot be refreshed or deployed.
- Every insight starts a debate about whether the numbers are right.
You probably hired the data engineer too early, or without a consumer, if:
- Pipelines run well but no one turns the data into decisions.
- The warehouse grows while business questions stay unanswered.
- The engineer is building infrastructure for use cases nobody has prioritized.
How in demand are data and AI roles in 2026?
Both roles are in high demand, with AI-focused roles ahead. On EcodeDash's Market Demand 2026 index, which draws on Grand View Research, Gartner and Qubit Labs reports, AI/ML engineers are rated 94% and data engineers 78% (EcodeDash, citing Grand View Research, Gartner and Qubit Labs 2025 to 2026 reports).
AI/ML engineers lead 2026 market demand at 94%, while data engineers sit at 78% (EcodeDash, citing Grand View Research, Gartner and Qubit Labs, 2026).
Share on LinkedIn · Share on X
There are two things to read into those figures. First, AI/ML engineer is not identical to data scientist, though the two overlap heavily and the same source groups data scientists and data engineers in its "AI & Data" category. Second, strong demand for AI talent increases the need for data engineering, because every AI initiative depends on clean, governed data. Salary is a separate question. Pay for both roles varies widely by region, seniority and stack, including between markets such as India, Singapore, Europe and the UAE, so benchmark against current local data before you set a budget.
How does staff augmentation let you add the second role when ready?
Staff augmentation adds pre-vetted specialists to your existing team on flexible terms. You can hire the first role now and bring in the second only when the data foundation justifies it. That approach avoids a months-long recruiting cycle for a role you may not need for another two quarters.
Three sequencing patterns work well:
- Engineer now, scientist on a pilot: Hire or augment a data engineer, then add an augmented data scientist for a 12-week model pilot once core tables are stable.
- Foundation sprint: Bring in an augmented data engineer for a focused pipeline build while you recruit a permanent data scientist.
- Rebalance an existing team: If you already hired a data scientist first, add a data engineer to unblock their work instead of replacing anyone.
EcodeDash supports these patterns with AI-curated, multi-stage vetted engineers, typically sharing profiles within 48 hours. Engagements can run hourly, by project or on a long-term retainer, and any developer who is not meeting expectations is replaced without extra cost.
What this means for you
- CTOs and technical founders: Run the five-point readiness check before approving any data science headcount. Fund the foundation that your AI roadmap depends on.
- VPs of Engineering: Define 90-day outputs for each data role before hiring, so you can spot a sequencing problem early.
- Product leaders: Bring one priority question with a named decision owner. A data scientist without one will struggle to show ROI.
- HR and talent acquisition leaders: Write job descriptions around the bottleneck rather than the title, and plan for the second role to arrive through flexible capacity.
Start with the bottleneck, not the job title
The right answer to data engineer vs data scientist depends on where value is currently stuck. If data cannot be trusted, start with engineering. If trusted data sits unused, start with science. Either way, plan the second hire before you need it.
If you are ready to sequence your data team, EcodeDash can help you add pre-vetted data engineers and data scientists to your team and scale each role when the timing is right.
Frequently asked questions
Can a data scientist become a data engineer?
Yes. Many data scientists already write SQL and Python, which gives them a head start. The move usually requires deeper skills in distributed systems, orchestration, testing and cloud infrastructure, which take deliberate practice to build.
Which is harder, data engineering or data science?
Neither is objectively harder; they are difficult in different ways. Data engineering demands software engineering rigor and systems thinking, while data science demands statistical judgment and the ability to frame business questions. The better fit depends on the person's strengths.
Who earns more, a data engineer or a data scientist?
Pay for both roles overlaps heavily and varies by region, seniority and specialization. AI-focused profiles often command a premium because demand is higher. Check current local salary data before you budget for either hire.
Do I need a data analyst before hiring either role?
Not always. A data analyst is useful when you need regular reporting from data that is already reliable. If your data is scattered or untrusted, a data engineer usually creates more value first.
Related resource
Engineering Talent and Hiring · Data and AI · data engineer vs data scientist · hire data engineer · hire data scientist